6G リンクレベル シミュレーション
R2026bこの参照シミュレーションでは、pre-6G リンクのスループットを測定する方法を示します。これは 5G に基づいていますが、5G システムよりも広い帯域幅とサブキャリア間隔を調査できます。また、並列処理を使用し、デスクトップまたはクラウドの複数のワーカーを使ってシミュレーションを高速化します。
はじめに
この例では、5G に基づいた pre-6G の物理リンクをシミュレーションします。送信機は、CRC 付加、LDPC 符号化、およびレート マッチングを使用してトランスポート ブロックを符号化した後、スクランブリング、QAM 変調、およびレイヤー マッピングによって物理チャネルを生成します。また、物理チャネルと基準信号の両方に SVD ベースのプリコーディングを適用します。その後、その結果を OFDM 変調し、クラスター遅延線 (CDL) MIMO 伝播チャネルを介して送信します。受信機はタイミング同期を実行し、信号を OFDM 復調し、チャネルを推定し、MMSE イコライゼーションを適用して、トランスポート チャネルを復号化します。このシミュレーションは HARQ もサポートしています。この例では、さまざまな SNR 点において、リンク スループットと前方誤り訂正前のビット エラー レート (BER) を測定します。
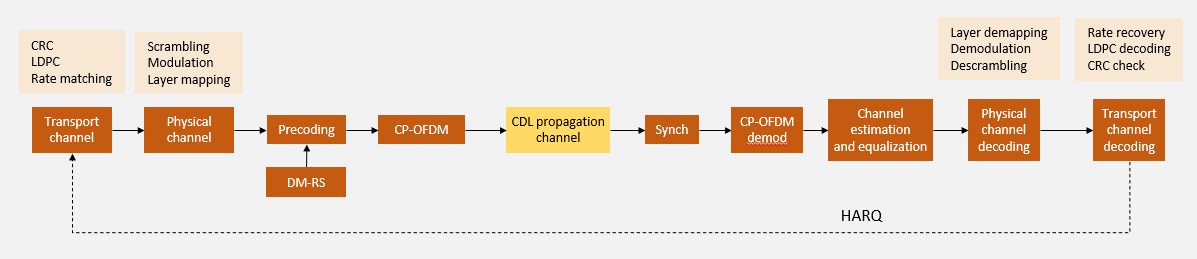
シミュレーション時間を短縮するために、この例では以下の高速化手法を実装しています。
GPU サポート (オプション)
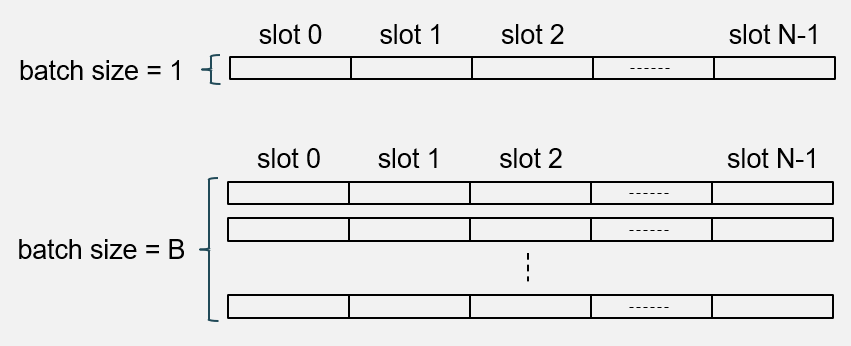
parforループを使用した並列実行: 処理は複数の CPU または GPU に分散されるバッチ処理: ベクトル化された配列演算を利用して、複数の独立した送信を単一のスロット反復にグループ化する
次の図はバッチ処理の概念を示しています。バッチサイズが 1 の場合、一度に 1 つのスロットのみが処理されます。バッチサイズが 1 より大きい場合、同じスロットの複数の独立したバージョンが同時に処理されます。この手法により、特に GPU を使用する場合にシミュレーションの速度向上を図ることができます。
シミュレーション パラメーターの設定
シミュレーションする SNR 範囲を指定します。
simParameters = struct();                       % Simulation parameters structure
simParameters.SNRdB = 0:5;                      % SNR range (dB)
統計的に十分なデータを得るため、この例では SNR 点ごとに複数の独立試行をシミュレーションします。1 回の試行は、連続する複数のスロットから成る独立したシミュレーションであり、情報ビット、加法性ノイズ、伝播チャネルがそれぞれ独立して発生することによって特徴付けられます。
simParameters.NumTrialsPerSNRPoint = 100; % Number of trials per SNR point物理レイヤーのパラメーター (リソース ブロック数、サブキャリア間隔、変調および符号化スキーム (MCS)、MIMO レイヤー数) を構成します。
simParameters.NSizeGrid = 52;                   % Number of resource blocks
simParameters.SubcarrierSpacing = 30;           % kHz
mcsTables = nrPDSCHMCSTables();
simParameters.MCSTable = mcsTables.QAM64Table;  % MCS table
simParameters.MCS = 18;                         % MCS
simParameters.NumLayers = 1;                    % Number of transmission layers
% PRB bundling
simParameters.PRGBundleSize = 4;                % Any positive power of 2, or [] to signify "wideband"
チャネル符号化と HARQ を構成します。試行ごとのスロット数は、NHARQProcesses*numel(rvSeq) に設定されており、すべての HARQ プロセスが少なくとも 1 回は完全な RV シーケンスを巡回できるようになっています。
% HARQ configuration
simParameters.NHARQProcesses = 16;
simParameters.EnableHARQ = true;
simParameters.rvSeq = [0 2 3 1];
% Number of slots per trial
simParameters.NumSlotsPerTrial = simParameters.NHARQProcesses*numel(simParameters.rvSeq);
送信アンテナと受信アンテナの数、およびチャネル パラメーターを設定します。
% Number of transmit and receive antennas
simParameters.NTxAnts = 4;
simParameters.NRxAnts = 2;

% CDL propagation channel parameters
simParameters.DelayProfile = "CDL-C";
simParameters.DelaySpread = 300e-9;
simParameters.MaximumDopplerShift = 5;
チャネル推定のタイプ (実用的または完全) を指定します。
simParameters.PerfectChannelEstimator = false; % Channel estimator configurationシミュレーションの高速化
シミュレーションの高速化オプションを構成します。この例は、3 つの高速化戦略をサポートしています。並列実行を有効にすると、並列プール内のワーカー間で処理を分散できます。GPU 計算が有効で、かつ複数の GPU が利用可能な場合、MATLAB は各ワーカーに対して異なる GPU を自動的に割り当てます。
デバッグ時など、順番に実行する場合は、EnableParallelExecution を false に設定してください。
simParameters.EnableParallelExecution = true;
simParameters.UseGPU = "off";              % Computation on GPU or CPU ("on"/"off"/"auto")
バッチ サイズは、ベクトル化演算を使用して何回分の独立した送信を同時に処理するかを決定します。たとえば、バッチサイズが 10 の場合、この例では 10 回の独立試行を同時にシミュレーションします。各試行は、NumSlotsPerTrial 個の連続したスロットで構成されます。バッチ サイズと試行との関係の詳細については、Accelerate 6G Link-Level Simulation with Batch Processing and GPU Executionの例を参照してください。
simParameters.BatchSize = 1; % Batch sizeMATLAB のグローバル乱数ストリームを初期化します。これは、parfor ループの外側で乱数発生器を制御します。
rng("default")サブストリームをサポートする個別の Threefry ストリームを作成します。parfor ループにおいて結果の再現性を確保するため、各ワーカーは独立したサブストリームを使用します。詳細については、ワーカー上の乱数ストリームの制御 (Parallel Computing Toolbox)およびparfor ループでの乱数の繰り返し (Parallel Computing Toolbox)を参照してください。
randStr = RandStream("Threefry",Seed=0);並列実行が有効になっている場合は、並列プールを作成し、ワーカー数を取得します。この例では、Accelerate Link-Level Simulations with Parallel Processingの例で紹介されている CPU 並列計算のアプローチを使用しています。
[maxNumWorkers,constantStream] = createParallelPool(simParameters.EnableParallelExecution,randStr);
シミュレーションの長さの表示
シミュレーションの長さは、次のパラメーターによって決まります。
NumTrialsPerSNRPoint— SNR 点ごとにシミュレーションされる独立試行の数。試行数を増やすことで、統計的カバレッジが向上します。NumSlotsPerTrial— 試行における連続スロットの数。HARQ を有効にすると、すべての HARQ プロセスが RV シーケンスを少なくとも 1 回は完了できるよう、各試行に十分なスロットが必要となります。この要件により、定常状態に至る前の初期過渡現象によってスループット統計が歪められることがなくなります。試行あたりの RV サイクル数を増やせば精度は向上しますが、一方でシミュレーション時間が増加し、並列処理の効率が低下します。並列処理の効率を高めるには、各ワーカー間に作業が均等に分散されるよう、試行を可能な限り短くするようにしてください。
シミュレーションするスロットの総数を表示します。
carrier = pre6GCarrierConfig(SubcarrierSpacing=simParameters.SubcarrierSpacing,NSizeGrid=simParameters.NSizeGrid);
totalNumSlots = ceil(simParameters.NumTrialsPerSNRPoint/simParameters.BatchSize)*simParameters.BatchSize*simParameters.NumSlotsPerTrial;
disp("Simulating "+totalNumSlots+" slots ("+(totalNumSlots)/carrier.SlotsPerFrame+" frames) per SNR point");
Simulating 6400 slots (320 frames) per SNR point
パラメーターの組み合わせの作成
チャネル シードを生成します。
chSeeds = randi([0 2^32-1],ceil(simParameters.NumTrialsPerSNRPoint/simParameters.BatchSize),1);
すべての SNR 点について、すべてのチャネル シードの組み合わせを行列 parameterCombinations に作成します。テーブル parameterCombinationsTable では、検証しやすいように、パラメーターの組み合わせが表形式で表現されています。
[parameterCombinations,parameterCombinationsTable] = allCombinations(simParameters.SNRdB(:), chSeeds);
スループットのシミュレーション
シミュレーションは、並列プールからワーカーを使用する並列ループに基づいています。並列実行が無効になっている場合、maxNumWorkers は 0 に設定されます。これにより、parfor ループは通常の for ループに変換されます。
シミュレーション コードをデバッグするには、EnableParallelExecution を false に設定して並列実行を無効にします。parfor ループの本体内にはブレークポイントを設定できませんが、ループ内から呼び出される関数には設定できることに注意してください。
% Create empty results table
resultTable = table(Size=[size(parameterCombinations,1) 10], ...
    VariableNames=["SNR","chSeed","numSlotsPerTrial","batchSize", ...
        "numCodedBits","numCodedBitErrors","numBits","numCorrectBits","numBlkErrors","numTrBlks"], ...
    VariableTypes=["double","uint32","uint32","uint32","uint32","uint32","uint32","uint32","uint32","uint32"]);

allSNRdB = parameterCombinations(:,1);
allChSeed = parameterCombinations(:,2);

% Parallel processing. simulate link for all parameter combinations
parfor (pforIdx = 1:size(parameterCombinations,1), maxNumWorkers)
    % Set random streams to ensure repeatability
    % Use substreams in the generator so each worker uses mutually independent streams
    stream = constantStream.Value;      % Extract the stream from the Constant
    stream.Substream = pforIdx;         % Set substream value = parfor index
    RandStream.setGlobalStream(stream); % Set global stream per worker

    % Per worker processing: pre-6G link
    snrdB = allSNRdB(pforIdx);
    chSeed = allChSeed(pforIdx);
    trialResults = hRunPre6GLink(simParameters, snrdB, chSeed);

    % Per worker results
    resultTable(pforIdx,:) = table(snrdB, chSeed, ...
        trialResults.NumSlotsPerTrial, trialResults.BatchSize, ...
        trialResults.NumCodedBits, trialResults.NumCodedBitErrors, ...
        trialResults.NumBits, trialResults.NumCorrectBits, trialResults.NumBlkErrors, trialResults.NumTrBlks);
end
スループット シミュレーション結果の要約
試行ごとの結果を SNR 点ごとに集計し、スループット指標を計算します。ビット エラー レート (BER) は、イコライゼーションの後、かつ前方誤り訂正処理の前に測定されます。
simThPut = processResults(resultTable,carrier.SlotsPerFrame);
disp(simThPut)
    SNR (dB)    NumSlots    NumTrBlks      BER       Throughput (Mbps)    Throughput (%)
    ________    ________    _________    ________    _________________    ______________

       0          6400        6400        0.17264         31.705              71.953
       1          6400        6400        0.15256         37.021              84.016
       2          6400        6400        0.13329         40.897              92.812
       3          6400        6400        0.11486         43.162              97.953
       4          6400        6400       0.097567         44.043              99.953
       5          6400        6400       0.081293         44.064                 100
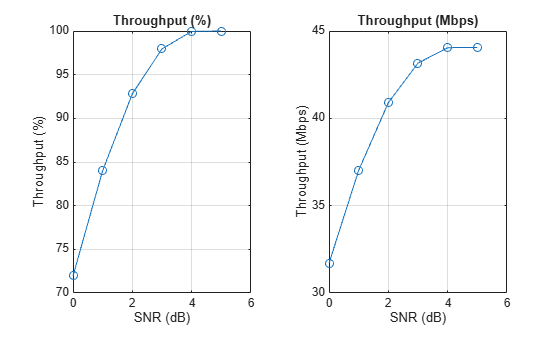
SNR に対するスループットをプロットします。
figure; tiledlayout(1,2); nexttile
plot(simThPut.("SNR (dB)"),simThPut.("Throughput (%)"),"o-"); grid on
title("Throughput (%)"); xlabel("SNR (dB)"); ylabel("Throughput (%)")
nexttile
plot(simThPut.("SNR (dB)"),simThPut.("Throughput (Mbps)"),"o-"); grid on
title("Throughput (Mbps)"); xlabel("SNR (dB)"); ylabel("Throughput (Mbps)")
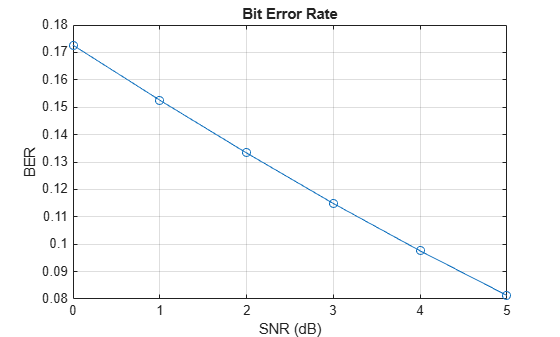
BER をプロットします。
figure
plot(simThPut.("SNR (dB)"),simThPut.("BER"),"o-"); grid on
title("Bit Error Rate"); xlabel("SNR (dB)"); ylabel("BER")
ローカル関数
function [maxNumWorkers,constantStream] = createParallelPool(enableParallelExecution,randStr)
%CREATEPARALLELPOOL Set up parallel pool and shared random stream.
%
%   [MAXNUMWORKERS,CONSTANTSTREAM] = CREATEPARALLELPOOL(ENABLEPARALLELEXECUTION,RANDSTR)
%   creates or reuses a parallel pool if ENABLEPARALLELEXECUTION is true
%   and the Parallel Computing Toolbox(TM) is available. Otherwise, falls
%   back to serial execution.
%
%   Inputs:
%       ENABLEPARALLELEXECUTION - Logical flag to enable parallel execution.
%       RANDSTR                 - RandStream object to share across workers.
%
%   Outputs:
%       MAXNUMWORKERS  - Number of workers (0 if running in serial).
%       CONSTANTSTREAM - parallel.pool.Constant wrapping RANDSTR, or a struct
%                     with field 'Value' when running in serial mode.

    if (enableParallelExecution && canUseParallelPool)
        pool = gcp; % create parallel pool, requires Parallel Computing Toolbox
        maxNumWorkers = pool.NumWorkers;
        constantStream = parallel.pool.Constant(randStr); %create a constant random stream to avoid unnecessary copying of the random stream multiple times to each worker
    else
        if (~canUseParallelPool && enableParallelExecution)
            warning("Ignoring the value of enableParallelExecution ("+enableParallelExecution+")"+newline+ ...
                "The simulation will run using serial execution."+newline+"You need a license of Parallel Computing Toolbox to use parallelism.")
        end
        maxNumWorkers = 0; % Used to convert the parfor-loop into a for-loop
        constantStream = struct("Value", randStr);
    end
end

function [combos,combosTable] = allCombinations(varargin)
%ALLCOMBINATIONS Cartesian product of parameter vectors.
%
%   [COMBOS,COMBOSTABLE] = ALLCOMBINATIONS(P1,P2,...,PN) returns every
%   combination of elements from the input vectors P1 through PN.
%
%   Inputs:
%       P1,...,PN - Numeric or logical vectors (row or column).
%
%   Outputs:
%       COMBOS      - M-by-N matrix where M = prod(numel(P1),...,numel(PN)).
%                     Each row is one combination of input values.
%       COMBOSTABLE - Table representation of COMBOS.

    n = nargin;
    assert(n >= 1, "Provide at least one parameter vector.");

    % Ensure each input is a column vector
    params = cellfun(@(v) v(:), varargin, "UniformOutput", false);

    % Create N-D grids
    grids = cell(1, n);
    [grids{:}] = ndgrid(params{:});

    % Flatten each grid to a column and concatenate into final matrix
    cols = cellfun(@(g) g(:), grids, "UniformOutput", false);
    combos = [cols{:}];
    combosTable = table(cols{:});
end

function simThPut = processResults(resultTable,slotsPerFrame)
%PROCESSRESULTS Aggregate per-trial results by SNR and compute metrics.
%
%   SIMTHPUT = PROCESSRESULTS(RESULTTABLE,SLOTSPERFRAME)
%   groups the per-trial results in RESULTTABLE by SNR, then computes
%   pre-FEC BER, throughput in Mbps, and throughput as a percentage.
%
%   Inputs:
%       RESULTTABLE   - Table with columns: SNR, numSlotsPerTrial, batchSize,
%                       numCodedBits, numCodedBitErrors, numBits,
%                       numCorrectBits, numBlkErrors, numTrBlks.
%       SLOTSPERFRAME - Number of slots per 10 ms frame.
%
%   Output:
%       SIMTHPUT - Table with columns: SNR (dB), NumSlots, NumTrBlks,
%                  BER, Throughput (Mbps), Throughput (%).

    frameDurS = 0.01; % 10 ms frame duration

    G = groupsummary(resultTable, "SNR", "sum", ...
        ["numSlotsPerTrial","numCodedBits","numCodedBitErrors","numBits","numCorrectBits","numBlkErrors","numTrBlks"]);

    batchSize = double(resultTable.batchSize(1));
    totSlots = G.sum_numSlotsPerTrial .* batchSize;

    % BER (pre-FEC)
    BER = double(G.sum_numCodedBitErrors) ./ double(G.sum_numCodedBits);

    % Simulation time
    numFrames = double(totSlots) ./ slotsPerFrame;
    simTimeS = numFrames .* frameDurS;

    % Throughput % = block success rate
    totBlks = totSlots;  % 1 trBlk per slot
    throughputPct = 100 .* (1 - double(G.sum_numBlkErrors) ./ double(totBlks));

    % Throughput Mbps = correctly decoded information bits / time
    throughputMbps = 1e-6 .* double(G.sum_numCorrectBits) ./ simTimeS;

    totTrBlks  = G.sum_numTrBlks;

    simThPut = table(G.SNR, uint32(totSlots), uint32(totTrBlks), BER, throughputMbps, throughputPct, ...
        VariableNames=["SNR (dB)","NumSlots","NumTrBlks","BER","Throughput (Mbps)","Throughput (%)"]);

    simThPut = sortrows(simThPut, "SNR (dB)", "ascend");
end
参考
pre6GCarrierConfig | pre6GPDSCHConfig

