lexrankScores
R2026bLexRank アルゴリズムによる文書スコアリング
説明
例
トークン化された文書の配列を作成します。
str = [
    "the quick brown fox jumped over the lazy dog"
    "the fast brown fox jumped over the lazy dog"
    "the lazy dog sat there and did nothing"
    "the other animals sat there watching"];
documents = tokenizedDocument(str)
documents =
4×1 tokenizedDocument:
9 tokens: the quick brown fox jumped over the lazy dog
9 tokens: the fast brown fox jumped over the lazy dog
8 tokens: the lazy dog sat there and did nothing
6 tokens: the other animals sat there watching
LexRank スコアを計算します。
scores = lexrankScores(documents);
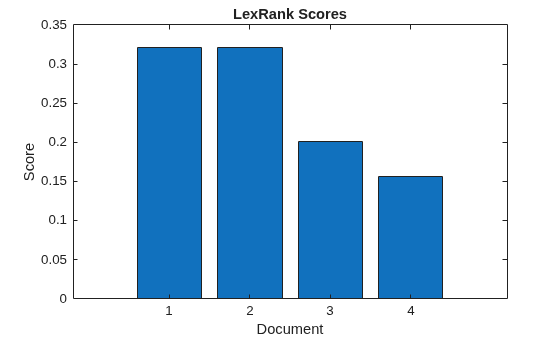
スコアを棒グラフで可視化します。
figure
bar(scores)
xlabel("Document")
ylabel("Score")
title("LexRank Scores")
sonnets.csv のテキスト データから bag-of-words モデルを作成します。
filename = "sonnets.csv";
tbl = readtable(filename,'TextType','string');
textData = tbl.Sonnet;
documents = tokenizedDocument(textData);
bag = bagOfWords(documents)
bag =
  bagOfWords with properties:

        NumWords: 3527
          Counts: [154×3527 double]
      Vocabulary: ["From"    "fairest"    "creatures"    "we"    "desire"    "increase"    ","    "That"    "thereby"    "beauty's"    "rose"    "might"    "never"    "die"    "But"    "as"    "the"    "riper"    "should"    "by"    …    ] (1×3527 string)
    NumDocuments: 154
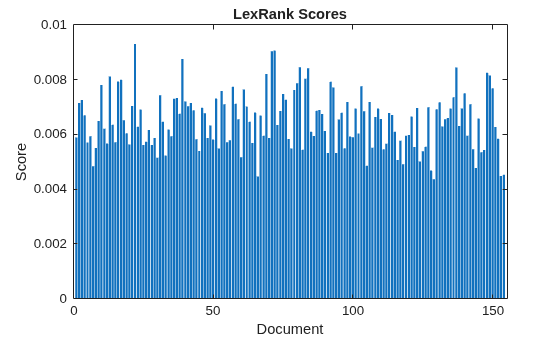
各ソネットの LexRank スコアを計算します。
scores = lexrankScores(bag);
スコアを棒グラフで可視化します。
figure
bar(scores)
xlabel("Document")
ylabel("Score")
title("LexRank Scores")
入力引数
出力引数
参照
[1] Erkan, Günes, and Dragomir R. Radev. "LexRank: Graph-based Lexical Centrality as Salience in Text Summarization." Journal of Artificial Intelligence Research 22 (2004): 457-479.
バージョン履歴
R2020a で導入

